NOTES / READING LIST AND GLOSSARY
Reading list: agents
A short, ordered reading path for building agents, from Anthropic's design guidance through ReAct, tool design and agent benchmarks, with why each is worth your time.
UPDATED 18 NOV 2026#agents#reading
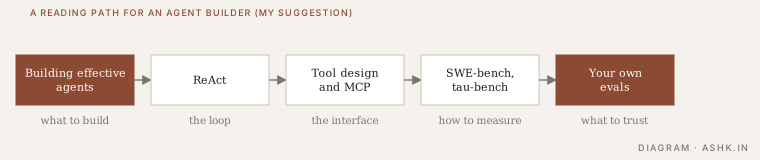 Diagram: my own suggested order.
- Building effective agents (Anthropic). Separates workflows from agents and advises starting with the simplest solution that works. The page notes that much of its tooling discussion has since changed, so read it for the principles.1 Matches workflows vs agents.
- ReAct. The reasoning-and-acting loop that most agent frameworks echo.2 See ReAct and planning.
- Model Context Protocol docs. The specification and guides for connecting models to tools and data.3 See MCP and tool design.
- SWE-bench. A benchmark of real software issues for coding agents.4 Variants are widely used, so see benchmarks for caveats.
- tau-bench. Tests tool-using agents in simulated user conversations, which matters for consistency over repeated runs.5 See agent evals.
Then stop reading and build your own eval set from real tasks: building eval sets.
Sources
- [1]Building effective agents — Schluntz and Zhang · Anthropic · 2024PARAPHRASED
- [2]ReAct: Synergizing Reasoning and Acting in Language Models — Yao et al. · 2022PARAPHRASED
- [3]Model Context Protocol specification — Model Context Protocol project · 2025PARAPHRASED
- [4]SWE-bench: Can Language Models Resolve Real-World GitHub Issues? — Jimenez et al. · 2023PARAPHRASED
- [5]tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains — Yao et al. · 2024PARAPHRASED